|
🤖
|
by aigenos · daily ai intelligence
dAIly
|
Jun 17 |
📌 Top Stories — Today's Biggest Moves (skim)
The day's highest-signal stories, ranked by builder-relevance — each linked to its primary source.


⚡ The Pulse — If You Only Read One Thing90 sec read
🎯 Today's Game-Changer
The release of GLM-5.2, a 753B parameter frontier-level model, marks a shift in the open-weights landscape. By providing a high-performance, MIT-licensed coding agent, this release enables enterprise-grade distillation and local-first reasoning capabilities that were previously gated behind proprietary APIs.
📍 In a Nutshell
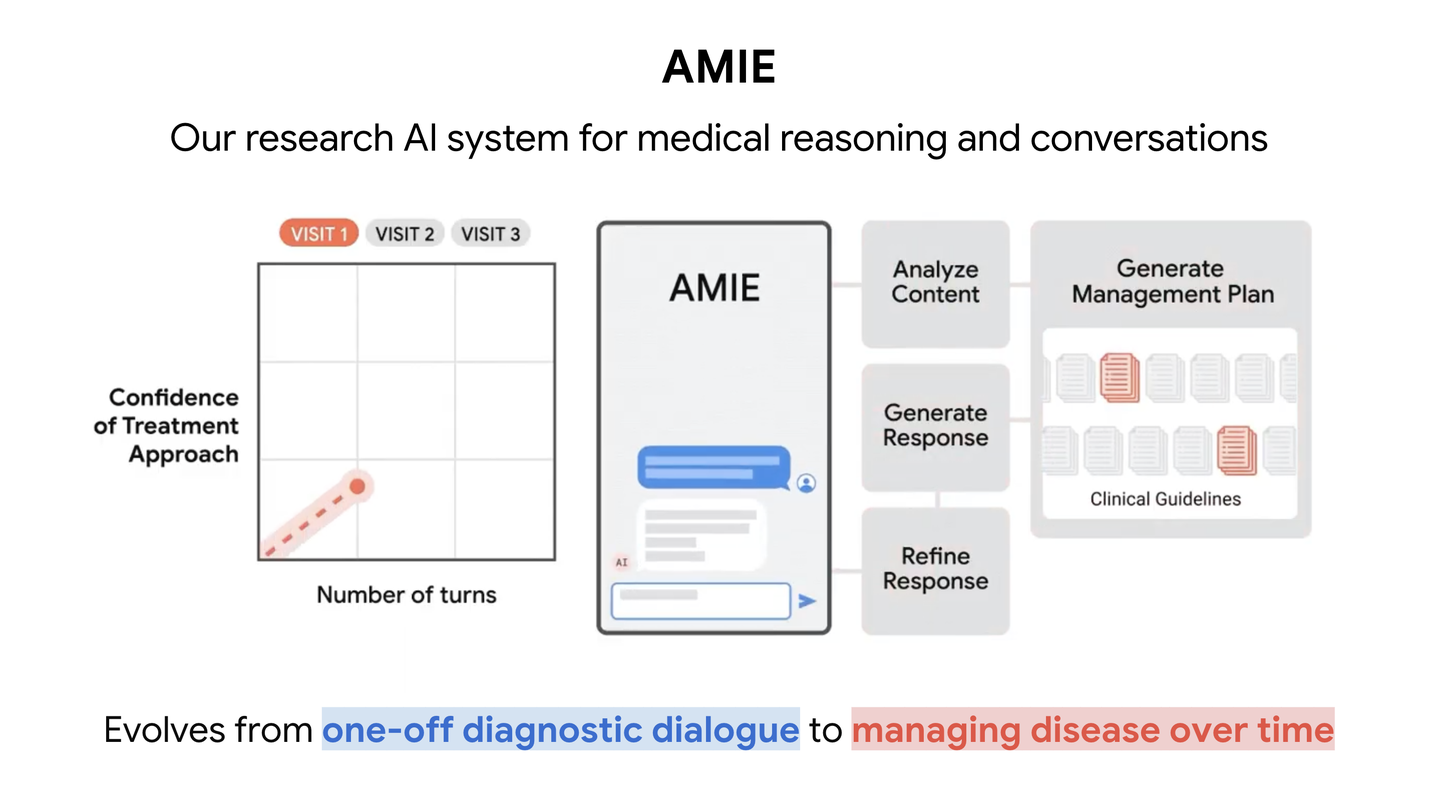
Google's AMIE demonstrated parity with primary care physicians in complex disease management in a recent Nature study.
MolmoMotion from AllenAI introduces language-guided 3D motion forecasting, bridging the gap between text prompts and physical world simulation.
AWS Bedrock AgentCore added continuous learning capabilities, allowing agents to ingest organizational and paid knowledge sources dynamically.
NVIDIA ACE launched new Unreal Engine 5 plugins for on-device AI companions, targeting low-latency gaming environments.
DRFLOW introduces a new benchmark for personalized workflow prediction, moving beyond simple report generation to concrete task execution.
Consumer Sentiment data shows 60% of US consumers find 'AI' in brand messaging a turnoff, signaling a need for "invisible" AI integration.
DeepSeek secured $7.4B in funding, signaling massive capital concentration in the race for reasoning-heavy foundation models.
🚀 Opportunity of the Day2 min read
Test-Oracle Auditor
- The gap: AI coding agents are generating massive volumes of test code (932,000+ PRs) that pass CI/CD but lack semantic validity, creating "smoke" tests that provide a false sense of security
- Why now: The recent quantification of agent-authored test failures proves that current linting and unit test runners are insufficient for AI-generated code; we need a secondary, logic-aware verification layer.
- Build as: A CI/CD plugin that acts as a "Test-Oracle Auditor," using a specialized reasoning model to verify that the test logic actually covers the edge cases introduced by the agent's code changes.
- Wedge & moat: Start by targeting enterprise security and reliability teams who are currently blocking AI agent adoption due to "test quality" concerns; the moat is the proprietary dataset of "failed vs. successful" agent-authored tests.
- Already heating up: The
HN Discussion.
- Closest existing solution: Standard tools like SonarQube or Codecov measure coverage but not logic-validity; there is no tool that specifically audits the *intent* of an AI-generated test against the *intent* of the code.
- First step this week: Build a prototype that takes a PR diff and the agent-authored test file, then uses a reasoning model (like GLM-5.2) to generate a "Test Logic Audit" report identifying missing assertions or redundant mocks.
📊 Stack Signals — Pick Your Tools3 min read
Benchmarks & Evals
Repo & Model Velocity
GLM-5.2: Trending for its 753B parameter scale; developers are currently exploring 4-bit quantization strategies to run this on non-unified memory clusters.
Funding & Launches — with Thesis
Brevio (Show HN): Thesis: The "browser-tool" utility layer is being commoditized; builders should focus on complex agentic workflows rather than single-task browser wrappers.
🔬 Deep Reads — For When You Have Time (skip if rushed)
📖 The One Deep Read
All Smoke, No Alarm: Oracle Signals in Agent-Authored Test Code by Banik et al. This paper is the definitive look at the "AI-test-debt" crisis. It analyzes nearly a million agent-authored PRs and reveals that AI agents frequently write tests that pass but fail to verify the actual code logic. Read it for: Understanding the specific failure modes of current coding agents and how to build a validation layer that prevents "ghost" test passing.
📑 Supporting Research
Stay focused on the logic-validation layer; the era of "AI-generated code is good enough" is ending as enterprise reliability requirements catch up to agent output.