
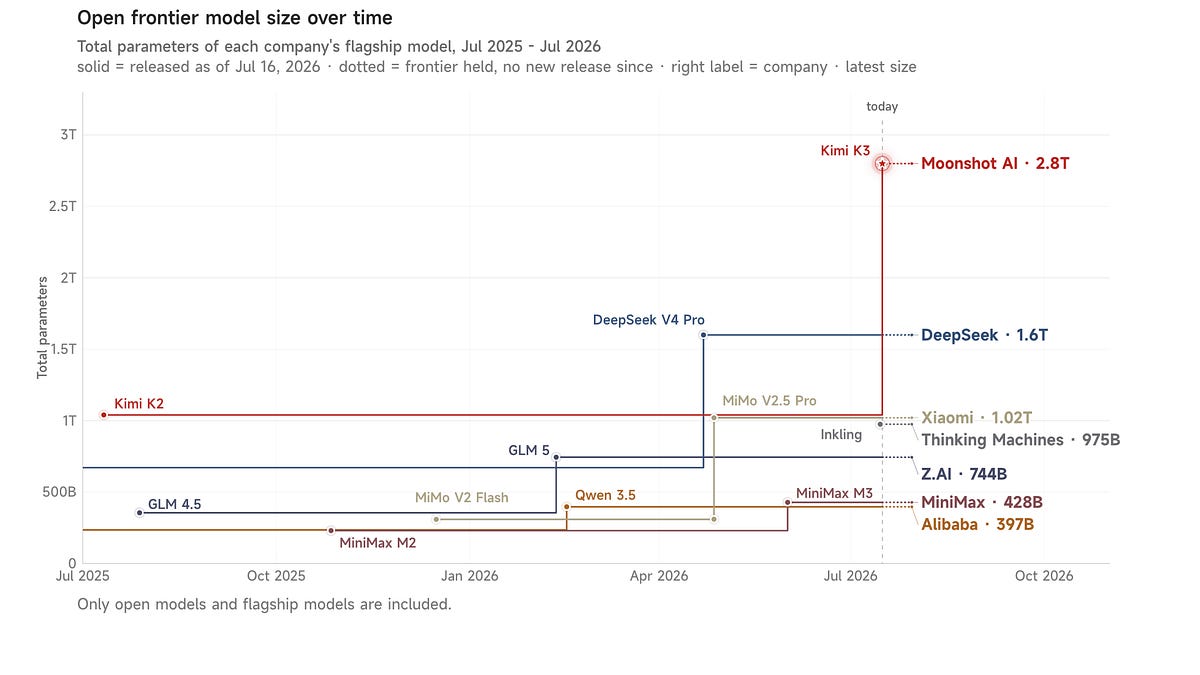
The frontier is shifting toward massive-scale open weights and embodied reasoning, with Moonshot AI’s Kimi K3 challenging the current dominance of closed-source models. For the builder, this week marks a pivot point where high-parameter open models and specialized video-action agents are finally becoming accessible for production-grade workflows.
📌 Top Stories — Today's Biggest Moves (skim)
The day's highest-signal stories, ranked by builder-relevance — each linked to its primary source.


⚡ The Pulse — If You Only Read One Thing90 sec read
The day's signal in 90 seconds — start here.
🎯 Today's Game-Changer
Moonshot AI has released Kimi K3, a 2.8 trillion parameter model described as their most capable to date. By offering performance competitive with Opus 4.8 and Sonnet 5 at significantly lower price points, K3 forces a re-evaluation of the "frontier gap" between proprietary labs and open-weight ecosystems, especially as the industry awaits its full open-weight release scheduled for July 20th.
📍 In a Nutshell
NVIDIA Nemotron 3 Embed takes the #1 spot on the Retrieval-Augmented Generation (RAG) benchmark (RTEB), signaling a major leap in agentic retrieval precision.
Grok 4.3 is now available on Amazon Bedrock, providing enterprise-grade access to xAI’s reasoning-heavy architecture.
LM Studio Bionic introduces an agentic layer for local models, allowing developers to orchestrate open-weight models with tool-calling capabilities.
Soofi S, a 30B parameter model from a German consortium, sets new benchmarks for multilingual performance in English and German.
RoboTTT introduces Test-Time-Training for robot policies, scaling visuomotor context to 8K timesteps to improve long-horizon embodied control.
Cars24 reports a 12% lead recovery rate using OpenAI-powered voice agents, demonstrating the immediate ROI of agentic workflows in high-volume sales.
Google Vids integrates Gemini Omni for real-time video editing and avatar generation, pushing multimodal capabilities into workspace productivity.
🚀 Opportunity of the Day2 min read
The single best thing to build right now.
Agentic Video-Action Policy Distillation
- The gap: Current Video MLLMs like
- Why now: The convergence of 8K-context robot policies and open-weight Video MLLMs allows for the first time the distillation of "world-model" reasoning into lightweight, real-time action policies.
- Build as: An OSS library that provides a distillation pipeline to convert Video MLLM reasoning traces into compact, low-latency policy heads for robotic hardware.
- Wedge & moat: Target the robotics research community and industrial automation firms; the moat is the proprietary dataset of "reasoning-to-action" pairs you curate during the distillation process.
- Already heating up: 76 upvotes on HF for VideoChat3 and significant interest in
- Closest existing solution: Open X-Embodiment provides the data, but lacks the specific distillation bridge for modern Video MLLMs to act as the "brain" for these policies.
- First step this week: Prototype a distillation loop using a pre-trained VideoChat3 model to predict the next 50ms of action tokens from a simulated robotic environment.
📊 Stack Signals — Pick Your Tools3 min read
What moved in tools, benchmarks & funding.
Benchmarks & Evals
- RTEB (Retrieval-Augmented Generation): NVIDIA Nemotron 3 Embed now leads, setting a new bar for embedding-based retrieval performance.
- Coding Benchmarks: Community debate is intensifying on whether Kimi K3 outperforms Opus 4.8 on real-world codebases, with
r/LocalLLaMA users actively stress-testing the model.
Repo & Model Velocity
Funding & Launches — with Thesis
🔬 Deep Reads — For When You Have Time (skip if rushed)
The one paper to actually read this week.
📖 The One Deep Read
VideoChat3: Fully Open Video MLLM for Efficient and Generalist Video Understanding by Li et al. This paper is essential because it bridges the gap between static image understanding and streaming video interaction, providing the architecture necessary for the next generation of video-based agents. Read it for: The technical breakdown of how they achieved efficient streaming interaction without the massive compute overhead of previous video models.
📑 Supporting Research